
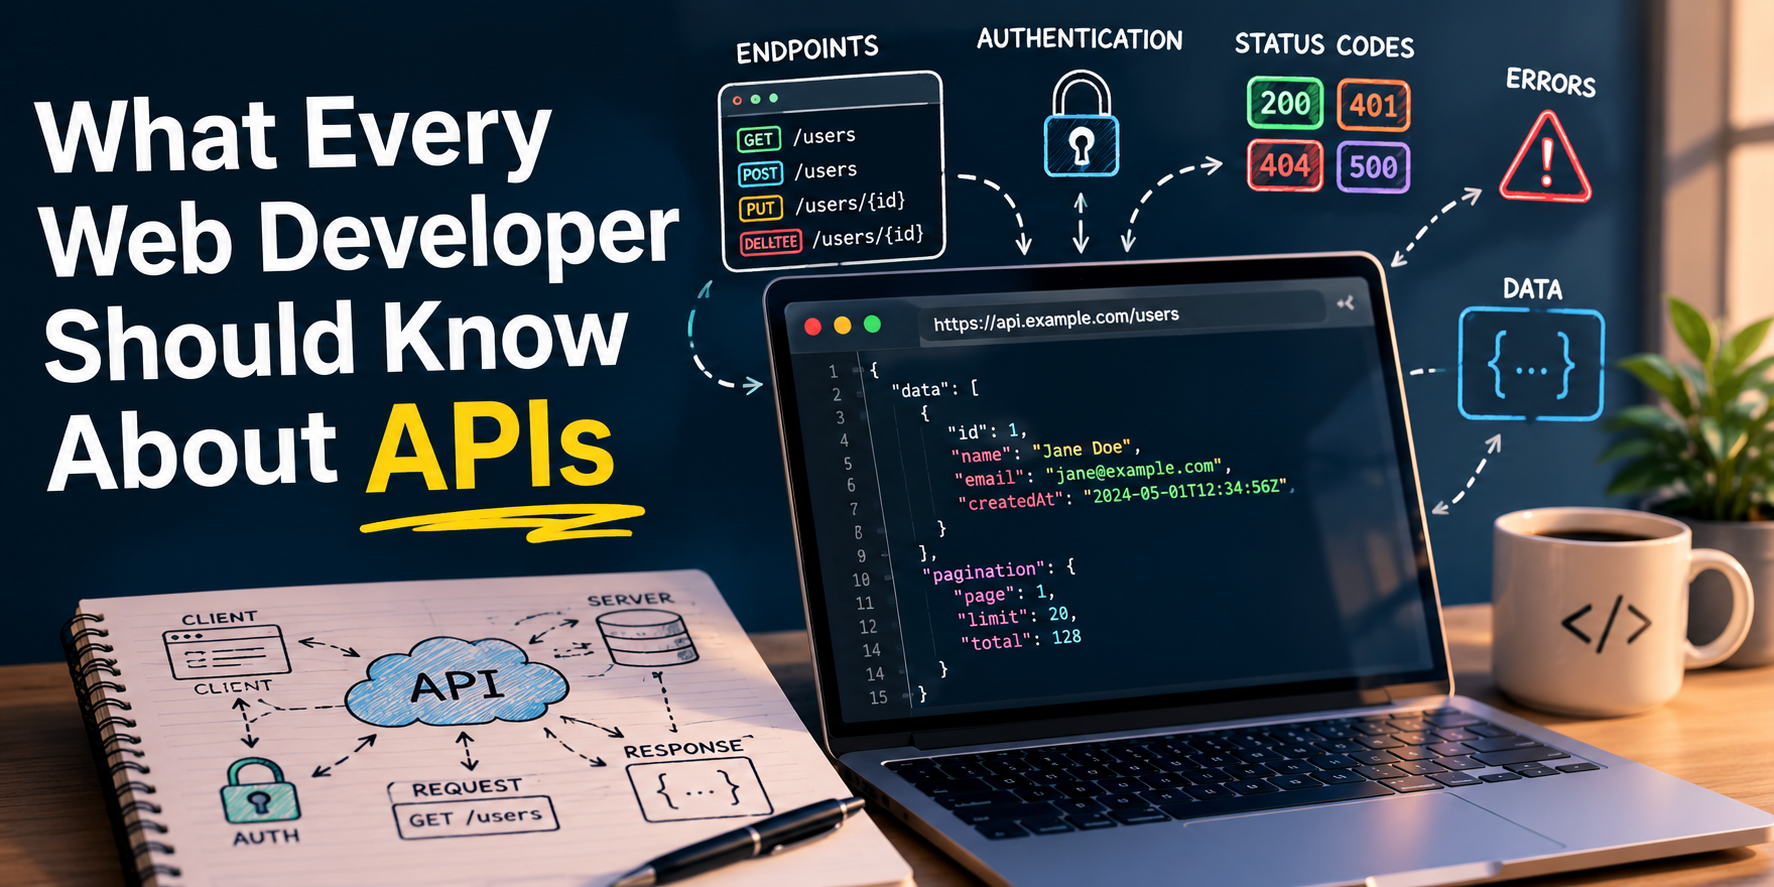
APIs are one of those things every web developer uses, but not every web developer understands deeply.
That is not meant as an insult. Most of us first encounter APIs as something we copy from the docs, wire into a frontend, and hope returns the JSON shape we expected. You make a fetch() call, pass a token, handle the response, and move on.
But the more web applications you build, the more obvious it becomes that APIs are not just plumbing. They are contracts. They define how systems talk to each other, how teams move independently, how data flows through a product, and how reliable your application feels to the people using it.
A good API makes development feel smooth. A bad API quietly spreads frustration through every layer of a project.
APIs Are Contracts, Not Just URLs
It is easy to think of an API as a collection of endpoints:
GET /usersPOST /ordersDELETE /sessions
That is only the surface.
The real API is the agreement between the client and the server. It includes the request format, the response format, the status codes, the authentication rules, the error structure, the rate limits, and the expectations around what changes are safe.
When a frontend depends on an API, it is depending on a promise.
If the backend suddenly renames a field from userId to id, that might seem minor on the server side. To the frontend, it can be a breaking change. If an endpoint sometimes returns an array and sometimes returns an object, every client has to defend against that uncertainty.
Good APIs reduce uncertainty.
Bad APIs make every caller guess.
HTTP Methods Matter
Web developers should understand the basic meaning of HTTP methods. They are not just decorative verbs.
GET is for retrieving data. It should not modify anything. A browser, crawler, cache, or proxy may treat a GET request as safe to repeat.
POST usually creates something or triggers an action.
PUT typically replaces a resource.
PATCH updates part of a resource.
DELETE removes a resource.
Can you build an API that ignores these conventions? Sure. Plenty of people do. But fighting HTTP usually makes your API harder to understand, harder to cache, harder to debug, and harder for other developers to use correctly.
The boring conventions exist for a reason.
Status Codes Should Tell the Truth
A surprising number of APIs return 200 OK for everything, then bury the real result inside the response body.
That is a mistake.
HTTP status codes are part of the API. Use them.
A successful request should usually return a 2xx code. A bad client request should return a 4xx code. A server problem should return a 5xx code.
Some common ones matter a lot:
200 OK201 Created204 No Content400 Bad Request401 Unauthorized403 Forbidden404 Not Found409 Conflict422 Unprocessable Entity429 Too Many Requests500 Internal Server Error
The exact code is not always worth arguing about forever, but the general category matters. A client should be able to tell the difference between “you sent bad data,” “you are not allowed to do this,” “this thing does not exist,” and “the server broke.”
That distinction affects error handling, retry behavior, logging, and user experience.
Error Responses Deserve Design
A clean success response is nice.
A clean error response is essential.
When something goes wrong, the client needs useful information. Not a stack trace. Not a vague “Something went wrong.” Not five different error formats depending on which part of the backend handled the request.
A decent error response might look like this:
{ "error": { "code": "INVALID_EMAIL", "message": "Email address is invalid.", "field": "email" }}
That gives the frontend enough information to show a useful message, highlight the right field, or handle the error programmatically.
The goal is not to expose every internal detail. The goal is to make failure predictable.
Predictable failure is a feature.
Authentication Is Not an Afterthought
Most APIs need some form of authentication. That might be a session cookie, an API key, a bearer token, OAuth, or something more specialized.
The important thing is to understand the tradeoffs.
Cookies work well for browser-based apps, especially when paired with proper HttpOnly, Secure, and SameSite settings.
Bearer tokens are common for APIs used by mobile apps, SPAs, CLIs, and third-party integrations.
API keys are simple and useful for server-to-server access, but they need to be treated like passwords. They should be scoped, revocable, and never exposed casually in frontend code.
Authentication answers the question, “Who are you?”
Authorization answers the question, “What are you allowed to do?”
Do not mix those up. A user being logged in does not mean they should be able to access every resource.
Versioning Saves Pain Later
Every API changes.
The question is whether it changes carefully or chaotically.
At some point, you will need to rename fields, remove fields, change behavior, split endpoints, or introduce a better data model. Without a versioning strategy, every change becomes risky.
There are several approaches:
/api/v1/users/api/v2/users
Or versioning through headers. Or maintaining backward-compatible changes for as long as possible.
The exact strategy matters less than having one.
The best API changes are additive. Adding a new field usually will not break old clients. Removing or renaming a field probably will. Changing the meaning of a field is even worse because the app may keep working while doing the wrong thing.
That is the most dangerous kind of bug.
Good APIs Are Boring in the Right Ways
Developers often want elegant abstractions, clever naming, or flexible endpoints that can do everything.
But the best APIs are usually boring.
They are consistent. They use predictable names. They return similar shapes. They paginate large lists. They document required and optional fields. They handle errors the same way everywhere.
For example, if one endpoint returns this:
{ "data": [...]}
and another returns this:
{ "items": [...]}
and another returns a raw array, every client has to remember those differences.
Consistency is kindness.
The same applies to naming. Pick a convention and stick with it. Use camelCase or snake_case, but do not randomly switch between both. Use createdAt everywhere, not created, created_at, timestamp, and dateCreated depending on the endpoint.
The API does not need to be clever. It needs to be dependable.
Pagination Is Not Optional
Sooner or later, a list endpoint will have too much data.
If your API returns all records by default, it is only a matter of time before the endpoint becomes slow, expensive, or unusable.
Pagination should be built in early.
There are two common styles:
?page=1&limit=50
or cursor-based pagination:
?cursor=abc123&limit=50
Page-based pagination is simple and works fine for many cases. Cursor-based pagination is better for large or frequently changing datasets.
The important thing is to avoid returning unbounded data. Your future self will thank you.
So will your database.
Frontend Developers Should Understand API Cost
From the frontend, an API call can feel cheap. It is just one line of code.
But every request has a cost.
It may hit a database. It may trigger a third-party service. It may require authentication checks, logging, validation, serialization, and network time. It may also block rendering or make the interface feel sluggish.
Frontend developers do not need to become backend engineers, but they should understand that API design affects performance.
Avoid unnecessary round trips. Fetch data in shapes that match the screen. Cache when appropriate. Debounce noisy requests. Do not refetch the same data every time a component blinks.
A fast frontend sitting on top of a chatty API will still feel slow.
Documentation Is Part of the Product
An undocumented API is not really finished.
Documentation does not need to be beautiful, but it does need to answer the practical questions:
What does this endpoint do?
What authentication is required?
What parameters does it accept?
What does a successful response look like?
What errors can happen?
Are there rate limits?
Can this change?
Tools like OpenAPI can help, but generated documentation is not a substitute for clear explanations. The best docs include examples, edge cases, and enough context for someone to understand not just how to call the API, but when and why to use it.
Good docs save time.
Bad docs create Slack messages.
No docs create folklore.
API Design Is User Experience for Developers
When we talk about user experience, we usually mean the people clicking buttons in the browser. But APIs have users too.
Their users are developers.
That means API design is a form of UX design. A confusing endpoint is like a confusing form. A vague error is like a useless alert box. An inconsistent response shape is like a button that moves around the page.
Developer experience matters because it affects speed, quality, and morale. A good API lets developers move with confidence. A bad API makes every task feel like an investigation.
This is especially important when the frontend and backend are built by different people or different teams. The API becomes the shared language of the product.
If that language is messy, the product gets messy.
Final Thoughts
Every web developer should know more about APIs than just how to call them.
You should understand that APIs are contracts. You should care about status codes, error formats, authentication, authorization, pagination, versioning, and documentation. You should recognize that API design affects performance, reliability, security, and developer happiness.
You do not need to obsess over purity. You do not need to turn every endpoint into an academic debate.
But you should care.
Because behind almost every modern web app is a conversation between systems. The quality of that conversation determines how much pain everyone else has to deal with.
Good APIs make software easier to build.
Bad APIs make everything downstream harder.


Leave a Reply